Public data in. Clean data out.
Kramer Labs builds small tools that read open sources like OpenAlex, sitemaps, and public job boards, and hand back something you can use: a spreadsheet, Markdown, or a ready-to-paste citation. Pay per result, or use the student tools for free.
PsychLab Assistant
Find the paper, copy the citation, and get back to writing. Built for George Fox psychology students in a palette that sits next to the university's own pages, and open to anyone.
Search 250M+ real papers
Every result comes from OpenAlex, so nothing is made up. Filter by year, free PDFs, or review articles.
APA 7 in one click
Copy a citation or a whole reading list, with BibTeX if your class uses it.
Plan a study
A coach, not an answer key: students choose the design and analysis and get feedback on their reasoning.
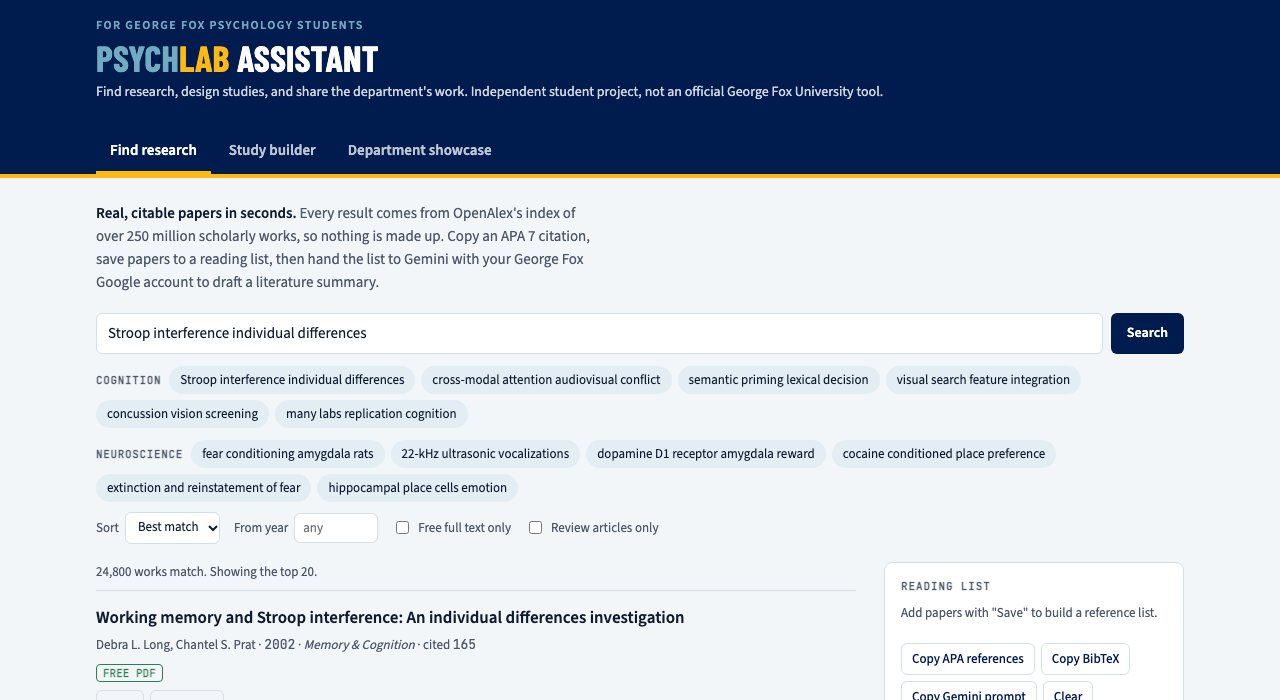
Independent student project, not an official George Fox University tool. Screenshot taken 31 Oct 2026 from the live site.
Need thousands of papers as data? PsychLab runs on the same source as Research Paper Search, our pay-per-use Actor with bulk DOI lookup and BibTeX.
Pay-per-use Actors
No subscription. You pay for results, and failed or skipped items are free. Prices below are live from the Store.
Research Paper Search
250M+ papers by keyword or DOI, with abstracts, free PDF links, APA 7 and BibTeX.
$2.00 per 1,000 papersCompany Jobs Scraper
Open roles from Greenhouse, Lever, Ashby, Workable and more, plus hiring signals.
$1.40 per 1,000 jobsWebsite SEO Audit
Titles, meta descriptions, H1s, canonicals, schema and alt text, with a 0–100 score and a fix list.
$7.00 per 1,000 pagesBroken Link Checker
Find 404s, dead domains and redirect chains, or bulk-check a list of URLs.
$0.80 per 1,000 linksSitemap URL Extractor
Every URL a site lists in its sitemaps, with last-modified dates.
$0.40 per 1,000 URLsWHOIS Domain Lookup
Bulk RDAP lookups: registrar, expiry dates, nameservers and DNS records.
$2.00 per 1,000 domainsWebsite to Markdown
Crawl a docs site or blog into clean Markdown for LLMs, RAG and AI agents.
$2.00 per 1,000 pages4 more in the queue
RSS Feed Reader, Website Tech Detector, Website Screenshot, and OCR & PDF Text. Built and tested, going live as Apify's daily publish limit allows.
Can AI assistants find Kramer Labs?
ChatGPT search, Perplexity, Claude and Google's AI answers build replies from pages they can crawl and cite. We audited our own presence, fixed what we could the same day, and re-checked.
4 of 6 problems fixed in one day.
The two left are about reputation, not setup: other sites have to mention us before AI search will. That takes posts, links and real users, so we're working on it in public.
Each square is one check, all the same size. A fix only counts once we verified it live (site returns 200, profile fields read back from each platform's API).
No owned website
Everything lived on apify.com and dev.to, and AI answers tend to cite a brand's own site to say what it is.
Fix: this site, with Organization schema, a sitemap, and an llms.txt that lists every product.
kramer-labs.netlify.app → 200
Brand search returns nothing
A web search for our account name returned zero Kramer Labs results. It surfaced Kramer Electronics instead.
query: "kramer_labs" apify → 0 of 23 results
Next: earn mentions off our own pages. Two new dev.to articles went up today, each linking back here.
Absent from category searches
For "apify actor broken link checker", results named seven competing Actors. Ours wasn't one of them.
query: apify actor broken link checker → brasspage, chris_elder, saliga, autoloom, savagnic, parseforge, jancurn
Next: Store ranking follows usage, so first runs matter most. How-to articles give AI assistants a page to cite.
Apify profile used a default description
The meta description was Apify's placeholder, and the profile had no bio or website.
Fix: bio, profile write-up and website link added.
api.apify.com/v2/users/kramer_labs → websiteUrl: kramer-labs.netlify.app
dev.to profile had no description
Crawlers had only a name to go on.
Fix: bio, education and website added.
dev.to/api/users/by_username?url=kramer_labs → website_url set
PsychLab had no public page
A search for a George Fox psychology research tool found faculty CVs and Digital Commons, but no tools. PsychLab was a local file.
Fix: now its own site at bruinpsych.netlify.app, linked from here and from the Research Paper Search page.
bruinpsych.netlify.app → 200
AI crawlers are allowed on Apify
Apify's robots.txt allows every crawler and permits search, AI input and AI training.
apify.com/robots.txt · Content-Signal: search=yes, ai-input=yes, ai-train=yes
Actor pages carry structured data
Each Store page has SoftwareApplication and Offer schema, plus a specific description with the price.
website-seo-audit · "…0-100 score, fix list, tech stack. $7 per 1,000 pages."
Both platforms serve llms.txt
apify.com and dev.to each publish an llms.txt, a clean map of the site for AI tools.
apify.com/llms.txt → 200 · dev.to/llms.txt → 200
Method: direct HTTP fetches of robots.txt, llms.txt and each profile page (title, meta description, H1, JSON-LD, word count), plus three web searches standing in for AI search retrieval, run once on 31 Oct 2026. Results vary by engine and by day. Want the on-page half for your own site? Website SEO Audit runs it automatically.